Archive of posts with category 'artificial intelligence'
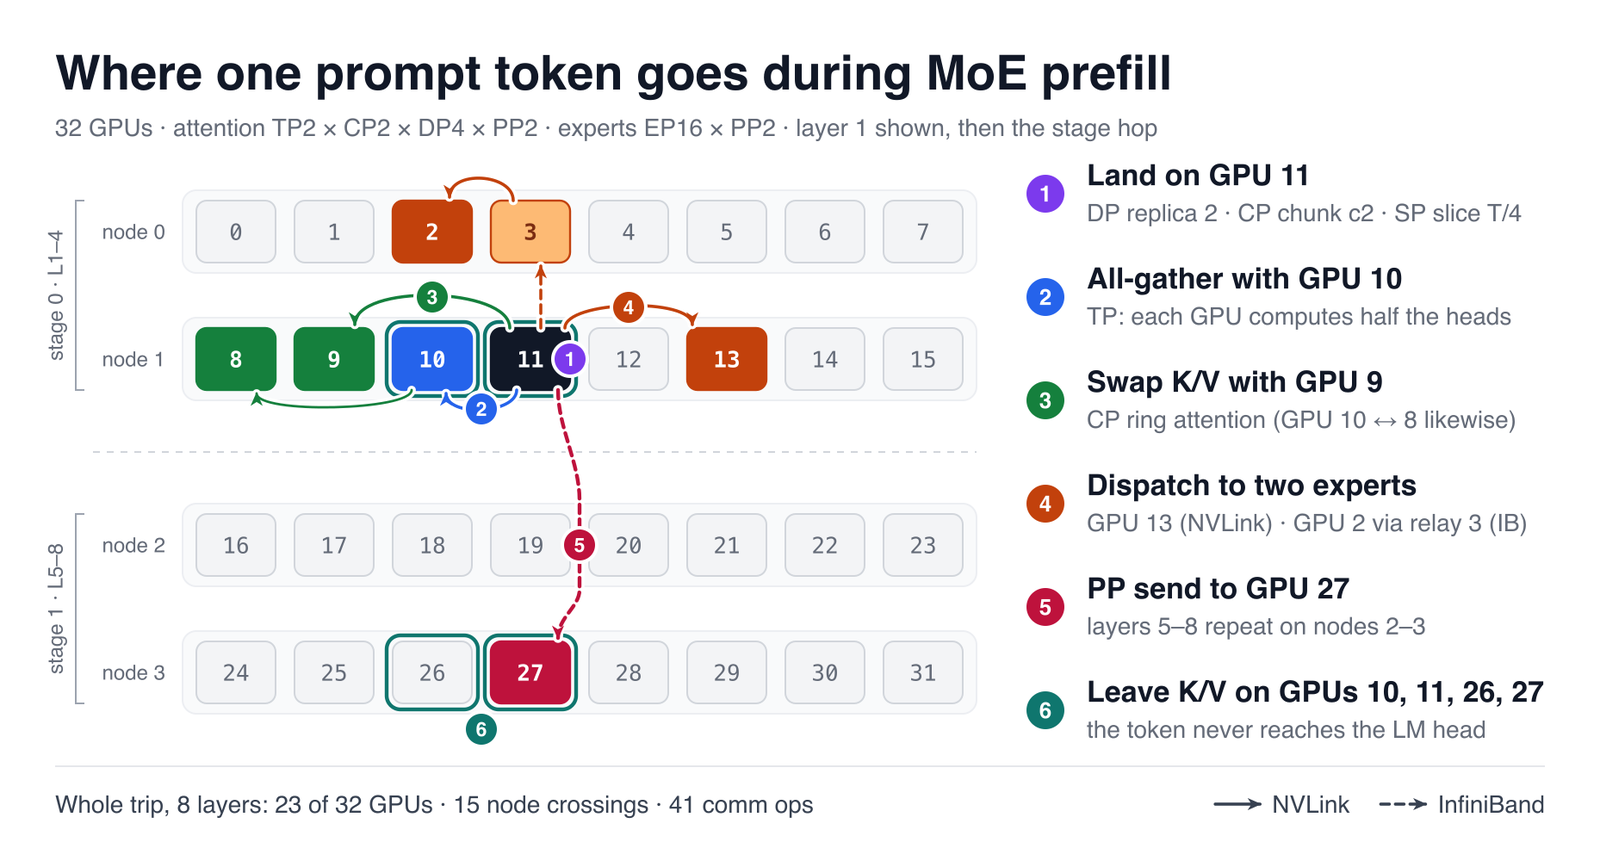
Trace a Token Through TP + CP + SP + EP + DP + PP in MoE Inference
How tensor, context, sequence, expert, data and pipeline parallelism compose in MoE prefill on 32 GPUs, and why experts force DP replicas into lockstep.
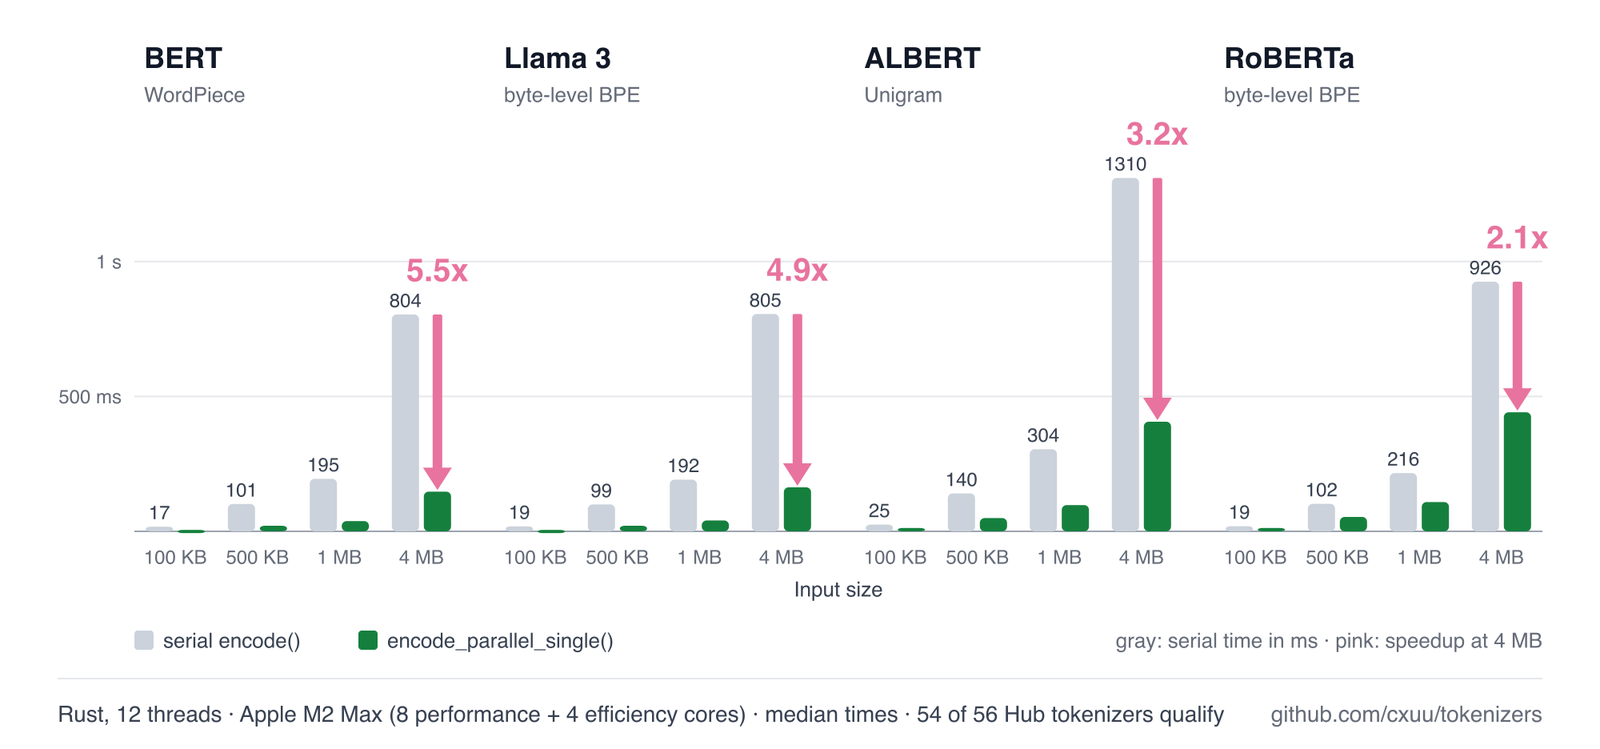
5.5x Faster HuggingFace Tokenizers for a Single Sequence
Use all cores on one long input with output identical to serial: Llama 3 tokenizes 4MB in 163ms, not 805ms, cutting text only where it's proven safe.
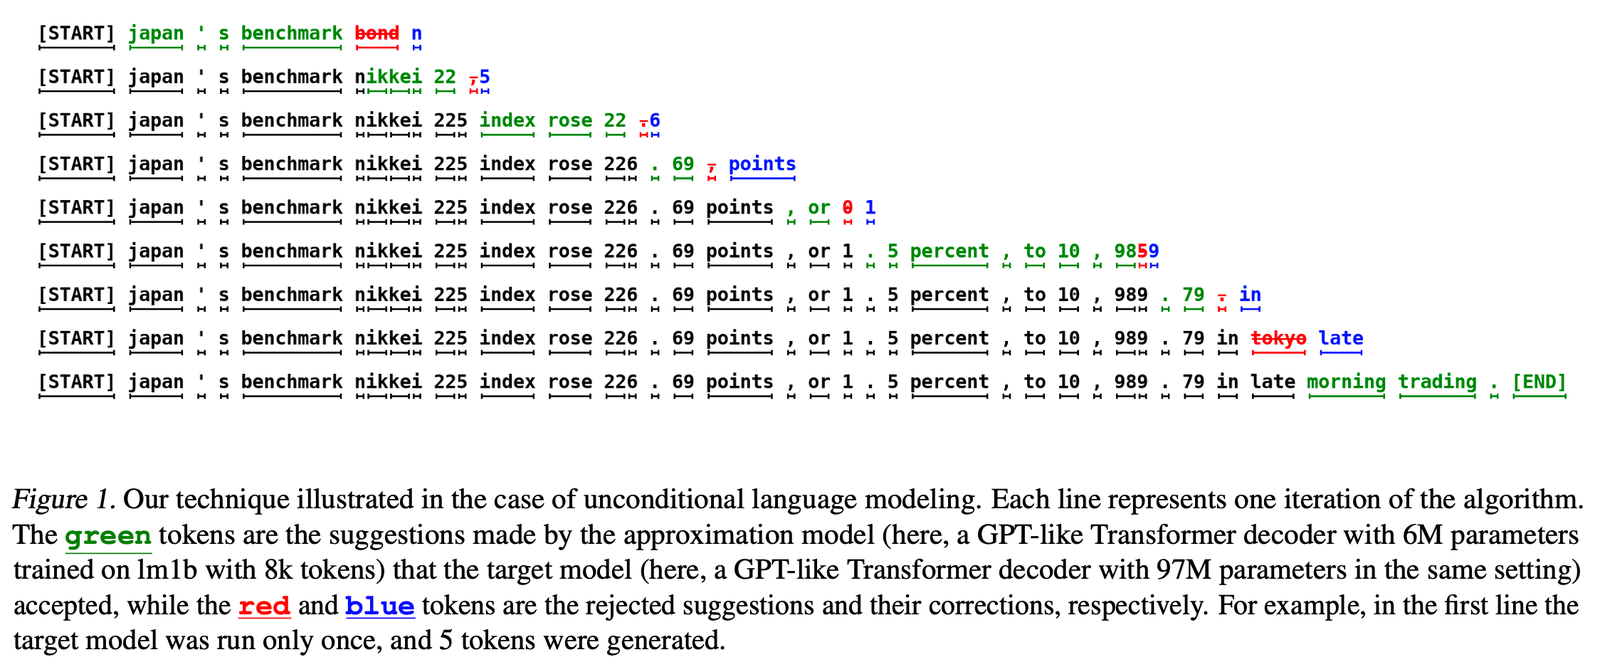
Accelerate LLM Inference with Speculative Decoding
Verify a draft model's tokens in one forward pass without changing the output distribution, or drop the draft model for Medusa heads and tree attention.
Parallelizing Multi-Head Attention
Why multi-head attention code transposes Q, K, V to (B, heads, T, head_dim) after the reshape: so one batched matmul computes every head in parallel.
 Never miss a story from me, subscribe to my newsletter